Structuring Local Text Folders for Clean Data Ingestion in Personal AI Retrieval-Augmented Generation (RAG) Systems
Structuring Local Text Folders for Clean Data Ingestion in Personal AI Retrieval-Augmented Generation (RAG) Systems
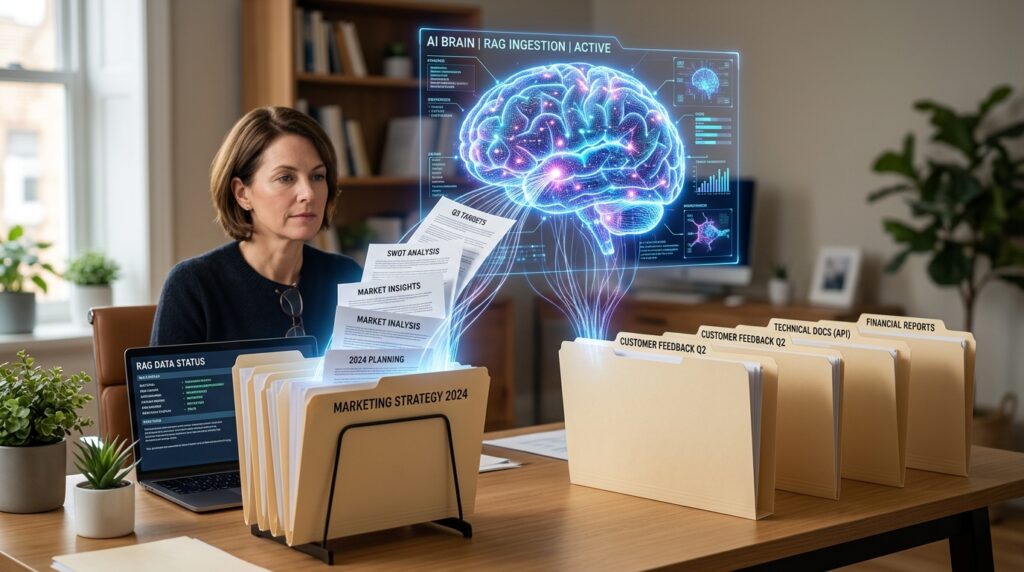
Personal artificial intelligence systems that are constructed via retrieval-augmented generation are highly dependent on the quality, structure, and consistency of the knowledge base that they are based upon. RAG systems, in contrast to standard programs that run on structured databases, take in unstructured or semi-structured text files and convert them into embeddings for semantic retrieval. Their purpose is to retrieve semantic information. It is important to note that the manner in which local text folders are structured has a direct influence on the accuracy of retrieval, the efficiency of indexing, and the relevancy of automatically produced replies. A clean and deliberate folder design enhances ingestion processes and increases the overall dependability of the system. Poorly organized data leads to noisy embeddings, redundant retrieval results, and lower contextual accuracy. On the other hand, a folder architecture that is clean and planned has the opposite effect. Because of this, the development of an environment for structured local text is a basic step in the process of constructing efficient personal AI knowledge systems.
Comprehending the Processes That RAG Systems Use to Handle Local Text Data
In most cases, retrieval-augmented generation systems start by scanning a directory of documents, then parsing the text content of those documents, and then transforming it into vector embeddings. The system is able to retrieve relevant chunks based on semantic similarity rather than keyword matching since these embeddings are kept in a searchable index inside the system. There is a strong correlation between the cleanliness of the segmentation and organization of the source data and the quality of the retrieval. In the event that files include a variety of themes, irregular formatting, or duplicated information, the embedding space will become congested and less discriminative. Assuring that each file provides information that is useful and contextually coherent to the knowledge base is the responsibility of a folder system that is well-structured.
An Analysis of the Significance of Logical Path Hierarchies
When it comes to structuring one’s own knowledge in a manner that is compatible with the way RAG systems organize and process information, a logical folder structure is absolutely necessary. It is possible for embeddings to maintain their semantic emphasis by way of grouping files according to domain, subject, or function. By separating things like personal documents, research summaries, reference materials, and technical notes, for instance, it is possible to limit the amount of overlap between ideas that are totally unrelated. This split reduces the amount of semantic space that exists inside each category, which results in improved retrieval accuracy. Not only does hierarchical organization simplify incremental intake, but it also makes it possible to add new data without causing any disruption to the structures that are already in place. This, over the course of time, establishes a foundation that is scalable for developing knowledge bases.
Making a distinction between raw notes and processed knowledge
It is essential to differentiate between raw input and processed or selected material in RAG-friendly storage systems, since this is one of the most significant structural elements. Documents that have been processed indicate material that has been cleansed, organized, and contextually full, while raw notes often include fragmented thoughts, incomplete concepts, or observations that have not been sufficiently developed. Because embeddings created from raw text have the potential to add noise into the system, combining these two forms of material may significantly reduce the quality of retrieval. In order to guarantee that only high-quality information is prioritized throughout the ingestion process, it is important to maintain distinct folders for raw data and curated data. This allows for the preservation of original content for the purposes of reference or correction.
Developing Conventions for Naming Files in Order to Achieve Semantic Clarity
The naming of files is an essential component in enhancing both the readability of files for humans and the indexing capabilities of machines. Instead of relying just on generic labels or timestamps, names need to be reflective of the content’s fundamental ideas, subjects, or functional groupings. When it comes to preprocessing and embedding creation, consistently adhering to naming standards helps to guarantee that similar documents are put together in a sensible manner. When retrieval algorithms include descriptive identifiers, they are able to infer contextual associations even before complete text analysis takes place. This extra layer of semantic communication helps to increase indexing accuracy and promotes search behavior that is more efficient inside huge databases.
Eliminating Duplication in the Knowledge Storage System
One of the most prevalent issues that arises in personal knowledge systems is the presence of redundant or duplicated material. This is particularly true in situations where notes are regularly altered or transferred across several places. Redundancy in RAG systems results in repeating embeddings, which may lead to biassed retrieval findings and resulting in a reduction in the variety of replies given. It is possible to reduce instances of duplicate content by organizing folders according to certain guidelines for version control and document consolidation. In order to guarantee that the system obtains the most relevant and authoritative version of information, it is essential to keep a single source of truth for each notion. Not only does this increase the quality of retrieval, but it also improves storage efficiency.
Performance Enhancement Through Folder Segmentation Optimization for Embedding
The most effective performance of embedding models is achieved when the input data is divided into cohesive theme pieces. By bringing together documents that are connected to one another prior to intake, folder-level segmentation contributes to the reinforcement of this structure. Because of this, preprocessing processes are able to implement consistent chunking algorithms dependent on the kind of material. For instance, the chunk sizes that are required for technical documentation could be different than those that are required for personal journals or research summaries. It is possible to guarantee that semantic representations will continue to be consistent and relevant for the whole of the dataset by aligning folder structure with predicted embedding behavior.
Working with Workflows That Incorporate Incremental Data Ingestion
Personal AI systems often undergo gradual development when fresh knowledge is introduced to them over the course of time. By enabling the incorporation of new files without requiring the reprocessing of the whole knowledge base, a folder system that is well-structured provides assistance for this scenario. In order to guarantee that only the areas of the dataset that are relevant are re-indexed whenever changes take place, it is important to clearly differentiate between stable archives and files that are regularly updated. This results in a reduction in processing overhead and an improvement in the responsiveness of the system. Additionally, incremental ingestion methods make it simpler to keep track of changes and provide version consistency across a variety of knowledge domains that are always growing.
Improving the Accuracy of Product Retrieval Through the Isolation of Content
When we talk about content isolation, we are referring to the process of isolating unrelated subject areas into separate storage domains. This enhances retrieval accuracy in RAG systems by decreasing semantic interference between ideas that are entirely unrelated to one another. Due to overlapping vocabulary or contextual ambiguity, embedding similarity scores may become less accurate when papers covering diverse topics are put together. This is because of the combination of the documents. In order to guarantee that retrieval queries function within more focused semantic limits, it is necessary to isolate material into specialized folders. During the generating process, this results in generated outcomes that are more exact and contextually relevant.
Preserving the Scalability of Knowledge Systems Over the Long Term
Because of the expansion of human knowledge bases, the importance of structural choices made early on in the design process of a system is rapidly growing. When vast amounts of data have been consumed, it is sometimes difficult to reorganize folder systems that are not well structured. The enforcement of uniform standards for categorization, naming, and data separation is one of the ways in which a scalable architecture prepares for forthcoming expansion. This eliminates the possibility of fragmentation and guarantees that the system will continue to be maintained over time. Those users who want to include large-scale personal archives, research collections, or professional material into their RAG systems should place a special emphasis on scalability.
Establishing a Trustworthy Data Base for Artificial Intelligence Retrieval Systems
When it comes to the construction of efficient personal AI retrieval-augmented generation systems, one of the key requirements is the restructuring of local text folders for the purpose of clean data input. In order to provide a solid basis for high-quality embeddings and accurate retrieval, users must first organize material into logical hierarchies, then separate raw data from processed data, then enforce consistent naming rules, and finally minimize duplication. In AI-driven knowledge systems, these behaviors have a direct impact on the performance, reliability, and scalability of the systems. The significance of maintaining a disciplined data organization system will continue to increase as the level of sophistication and widespread use of personal AI technologies increases. A local text environment that is well-structured guarantees that retrieval systems work with clarity, accuracy, and long-term efficiency, which eventually enables more intelligent and context-aware interactions across different types of artificial intelligence.